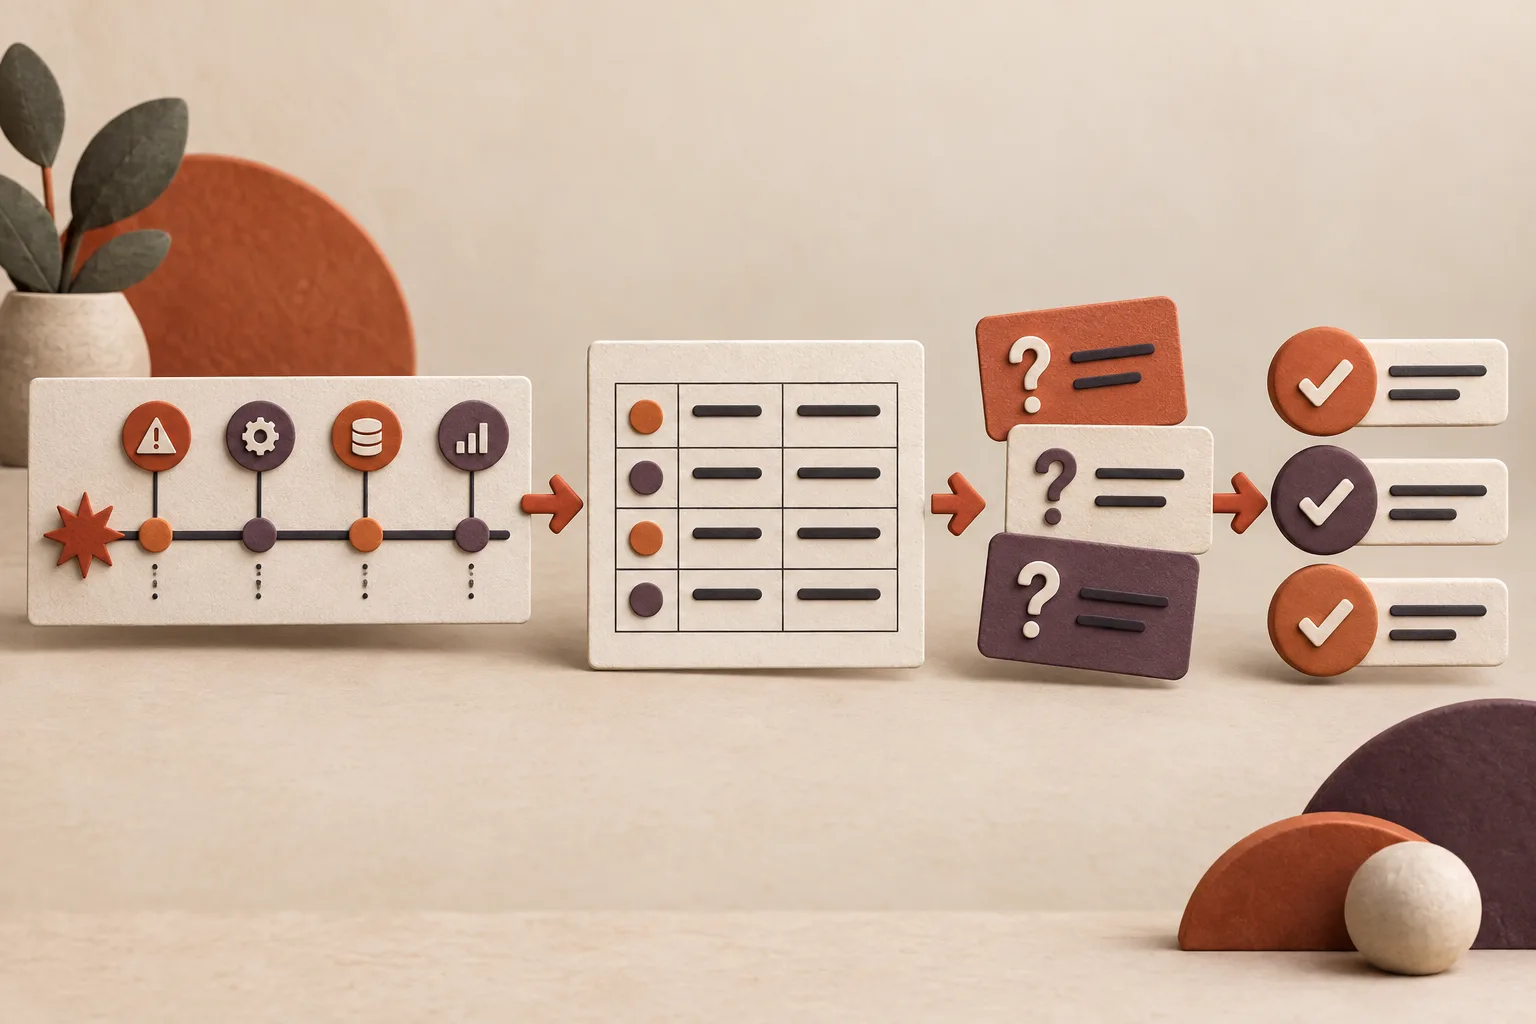
Incidents have a repeated shape: assemble a timeline, capture customer impact, preserve evidence and uncertainty, assign stated follow-ups, and publish a blameless internal brief. AI can accelerate that assembly when the incident commander remains the reviewer.
The workflow must never manufacture root cause, action owners, or blame from a messy record. Its best result may be a complete timeline with visible gaps ready for human analysis.
Part 01 · Assemble the incident record
Assemble the incident record
Incidents already have a repeated shape
Most incidents require the same core artifact: timeline, impact, evidence, unknowns, actions, and decisions. Standardizing that shape reduces assembly work without standardizing the investigation conclusion.
One useful email a week
Get one workflow teardown a week.
A practical look at how a real repeated job becomes a reliable AI workflow — inputs, review points, and the failure modes to avoid.
By subscribing, you agree to receive Grokkit’s weekly workflow teardown. Unsubscribe anytime.
Inputs: timeline, tickets, chats, customer notes
Name the permitted logs, tickets, chat excerpts, status updates, customer records, and notes. Capture timestamps and source references so the timeline can be inspected later.
Output: what happened, evidence, unknowns, follow-ups
The brief should distinguish observed events from hypotheses, attach material evidence, show gaps, and list only follow-ups that have an explicit owner or decision path.
Blameless structure as the definition of done
Use a structure focused on systems, evidence, conditions, decisions, and learning. Do not turn incomplete records into personal judgment or imply culpability through generated language.
No invented root cause
Root cause remains unknown until the responsible investigation establishes it. The workflow may list hypotheses and evidence gaps, but it must not convert correlation into a conclusion.
Part 02 · Protect analysis and customers
Protect analysis and customers
Customer-impact section with source tags
State impact using approved customer, support, or status evidence and tag the source. Avoid estimating affected customers, duration, or harm when the record does not support it.
Action items with owners only if stated
Include an owner only when a source records one or an incident commander assigns it during review. Otherwise list the follow-up as unowned and escalate the assignment.
Sev levels and escalation path
Use the organization’s stated severity definitions and escalation process. The workflow can classify supplied evidence against the rubric but cannot silently downgrade or close an incident.
Reviewer: incident commander
The incident commander or named delegate verifies timeline, impact, framing, actions, and audience before publication. A generated brief is an input to command, not a substitute for it.
Internal brief vs customer note
Keep causal detail, internal hypotheses, and operational constraints in the internal brief. Prepare a separate customer note with verified impact, next update, and approved commitments.
Part 03 · Review the after-action brief
Review the after-action brief
Connecting to release-readiness and support skills
An approved incident outcome can inform release readiness and support escalation rules. Preserve the source and avoid treating a postmortem hypothesis as a permanent policy.
Test cases: clean incident, messy timeline, missing logs
Test a straightforward incident, a contradictory multi-team timeline, and a case with missing logs. A safe workflow shows uncertainty and requests evidence instead of producing a false complete story.
Guardrails on speculation and blame
Block unsupported causal claims, named blame, customer commitments, and security conclusions. The workflow should flag the need for investigation or authorized review.
Time-to-first-draft while memory is fresh
Measure time from source cutoff to a reviewable timeline and brief. Faster assembly helps learning only if source links and unknowns survive the speed.
Learning library over time
Store approved postmortems with tags for incident type, controls, and lessons, subject to access policy. The library should inform tests and process changes without becoming unreviewed model training context.
Part 04 · Build institutional learning
Build institutional learning
Versioning when the incident process changes
Update severity definitions, source rules, output sections, and tests together when the incident process changes. Publish the change so responders know what the next brief requires.
Metrics: completeness of actions, time to published brief
Track required-section completeness, time to reviewed brief, action ownership, reopened findings, and missing-evidence rate. Do not use a short draft time as evidence of an effective incident process.
When the skill should only assemble a timeline
Limit the workflow to timeline assembly when root-cause analysis is sensitive, evidence is incomplete, or the investigation requires specialist judgment. A well-attributed timeline is still valuable progress.
Multi-team incidents and conflicting accounts
Preserve each account, source, timestamp, and conflict rather than selecting the most fluent narrative. Route contradictions to the incident commander for resolution or explicit uncertainty.
Custom workflow for after-action work
Grokkit can package your incident sources, blameless structure, reviewer gate, customer-safe split, test cases, and versioning practice around one after-action artifact.